A full polishing range.
From cutting and one-step correction to final finishing.
Specialist chemistry. Expert application.
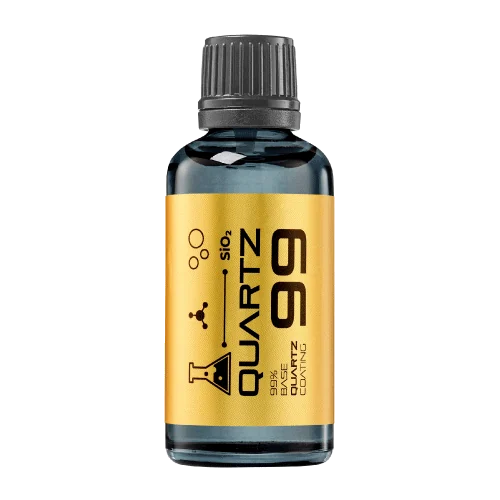 QUARTZ99 / CERAMIC BASE COAT
The foundation of your coating system.
A layerable quartz base coat designed for mechanical protection. Pair it with a suitable top coat to create the final finish.
For application by NANOLAB certified installers only.
Four formulas. Extended working time. Find the coating for your finish.
Explore the BEAST family of ceramic coatings.
Find the coating for each exterior surface.
 PPF & VINYLGLOSSProtection for glossy films and wraps.Discover
 MATTE & SATINMATTEProtection that respects the finish.Discover
 GLASSWINDOWSExplore dedicated glass protection.Discover
 WHEEL PROTECTIONWHEELSA dedicated coating for your wheels.Discover
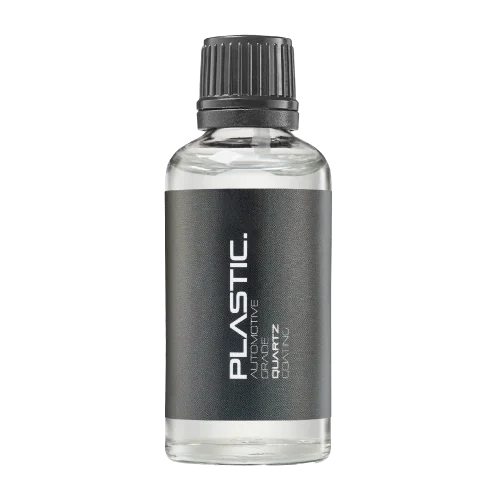 TRIM PROTECTIONPLASTICProtection for plastic surfaces.Discover
Dedicated care for the surfaces inside.
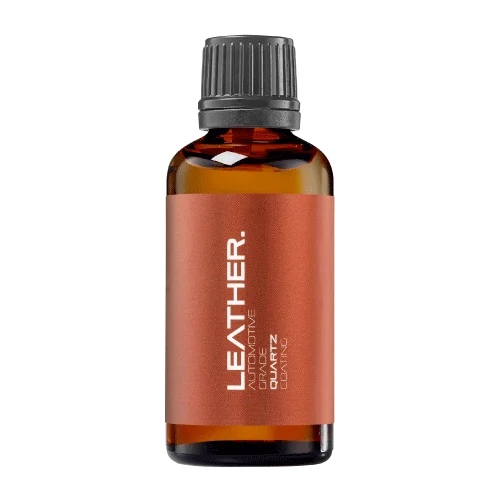 LEATHER SURFACESLEATHERDiscover NANOLAB leather protection.Discover PLASTIC SURFACESPLASTICProtection for interior plastic surfaces.Discover TEXTILE SURFACESFABRICExplore the latest fabric formulation.Discover
Spray protection, maintenance and upcoming wash products.
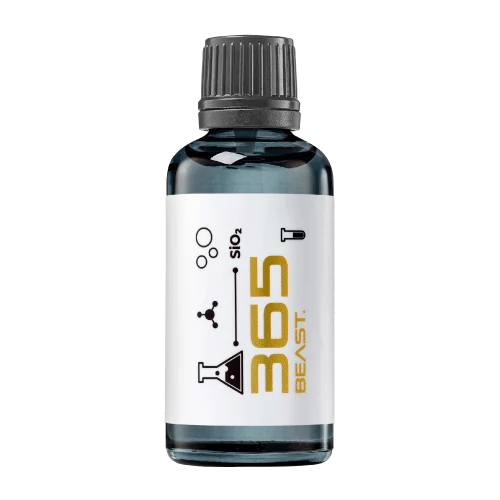 MAINTENANCEBEAST 365Explore the BEAST maintenance range.Discover
Next in washing, cleaning & care.
Ceramic protection for boats and yachts.
An easy-to-apply ceramic coating with an established track record on boats and yachts around the world.
Results vary with surface preparation, exposure and maintenance.
Read 50 MARINE guides →Explore MARINEProtection for the surfaces you live with.
A look at what we’re developing.
From cutting and one-step correction to final finishing.
A wider range for professional vehicle care.
Taking shape alongside BEAST & MATRIX.
Practical guidance for your next coating project.
Explore all guides →
A repeated row may be an accidental duplicate or a legitimate repeat measurement. Use sample, time and measurement identifiers to distinguish the two before cleaning a coating-trial dataset.
Updated · NANOLAB Knowledge
Removing every repeated value can erase valid observations, while retaining copied records can give one sample too much influence. The data structure should identify the event that each row represents. Preserve the original import and record any correction so the final analysis remains traceable.
Illustrative example: two measurements on the same panel happen to have the same value. They are not duplicates merely because the number matches. By contrast, importing the same instrument file twice can create duplicate events even if the rows look like a larger sample set.
Do not delete inconvenient observations through an automated deduplication rule that ignores their meaning. This guide does not specify a database design. It establishes the need to identify the measurement event before deciding whether a row is redundant or part of the evidence.
Ask NANOLAB about the exact product and intended use. Use the current product documentation for formulation-specific instructions.
Data exclusions can be legitimate, but selective removal after seeing unfavourable results undermines the comparison.
A score compresses observations into a category. Retaining the underlying observations allows later review when the scoring rule is questioned.
A comma or full stop can represent a decimal separator differently across data sources. Validate imported numeric fields before using coating measurements or quantities in calculations.